How to Run an Agent Loop That Actually Converges
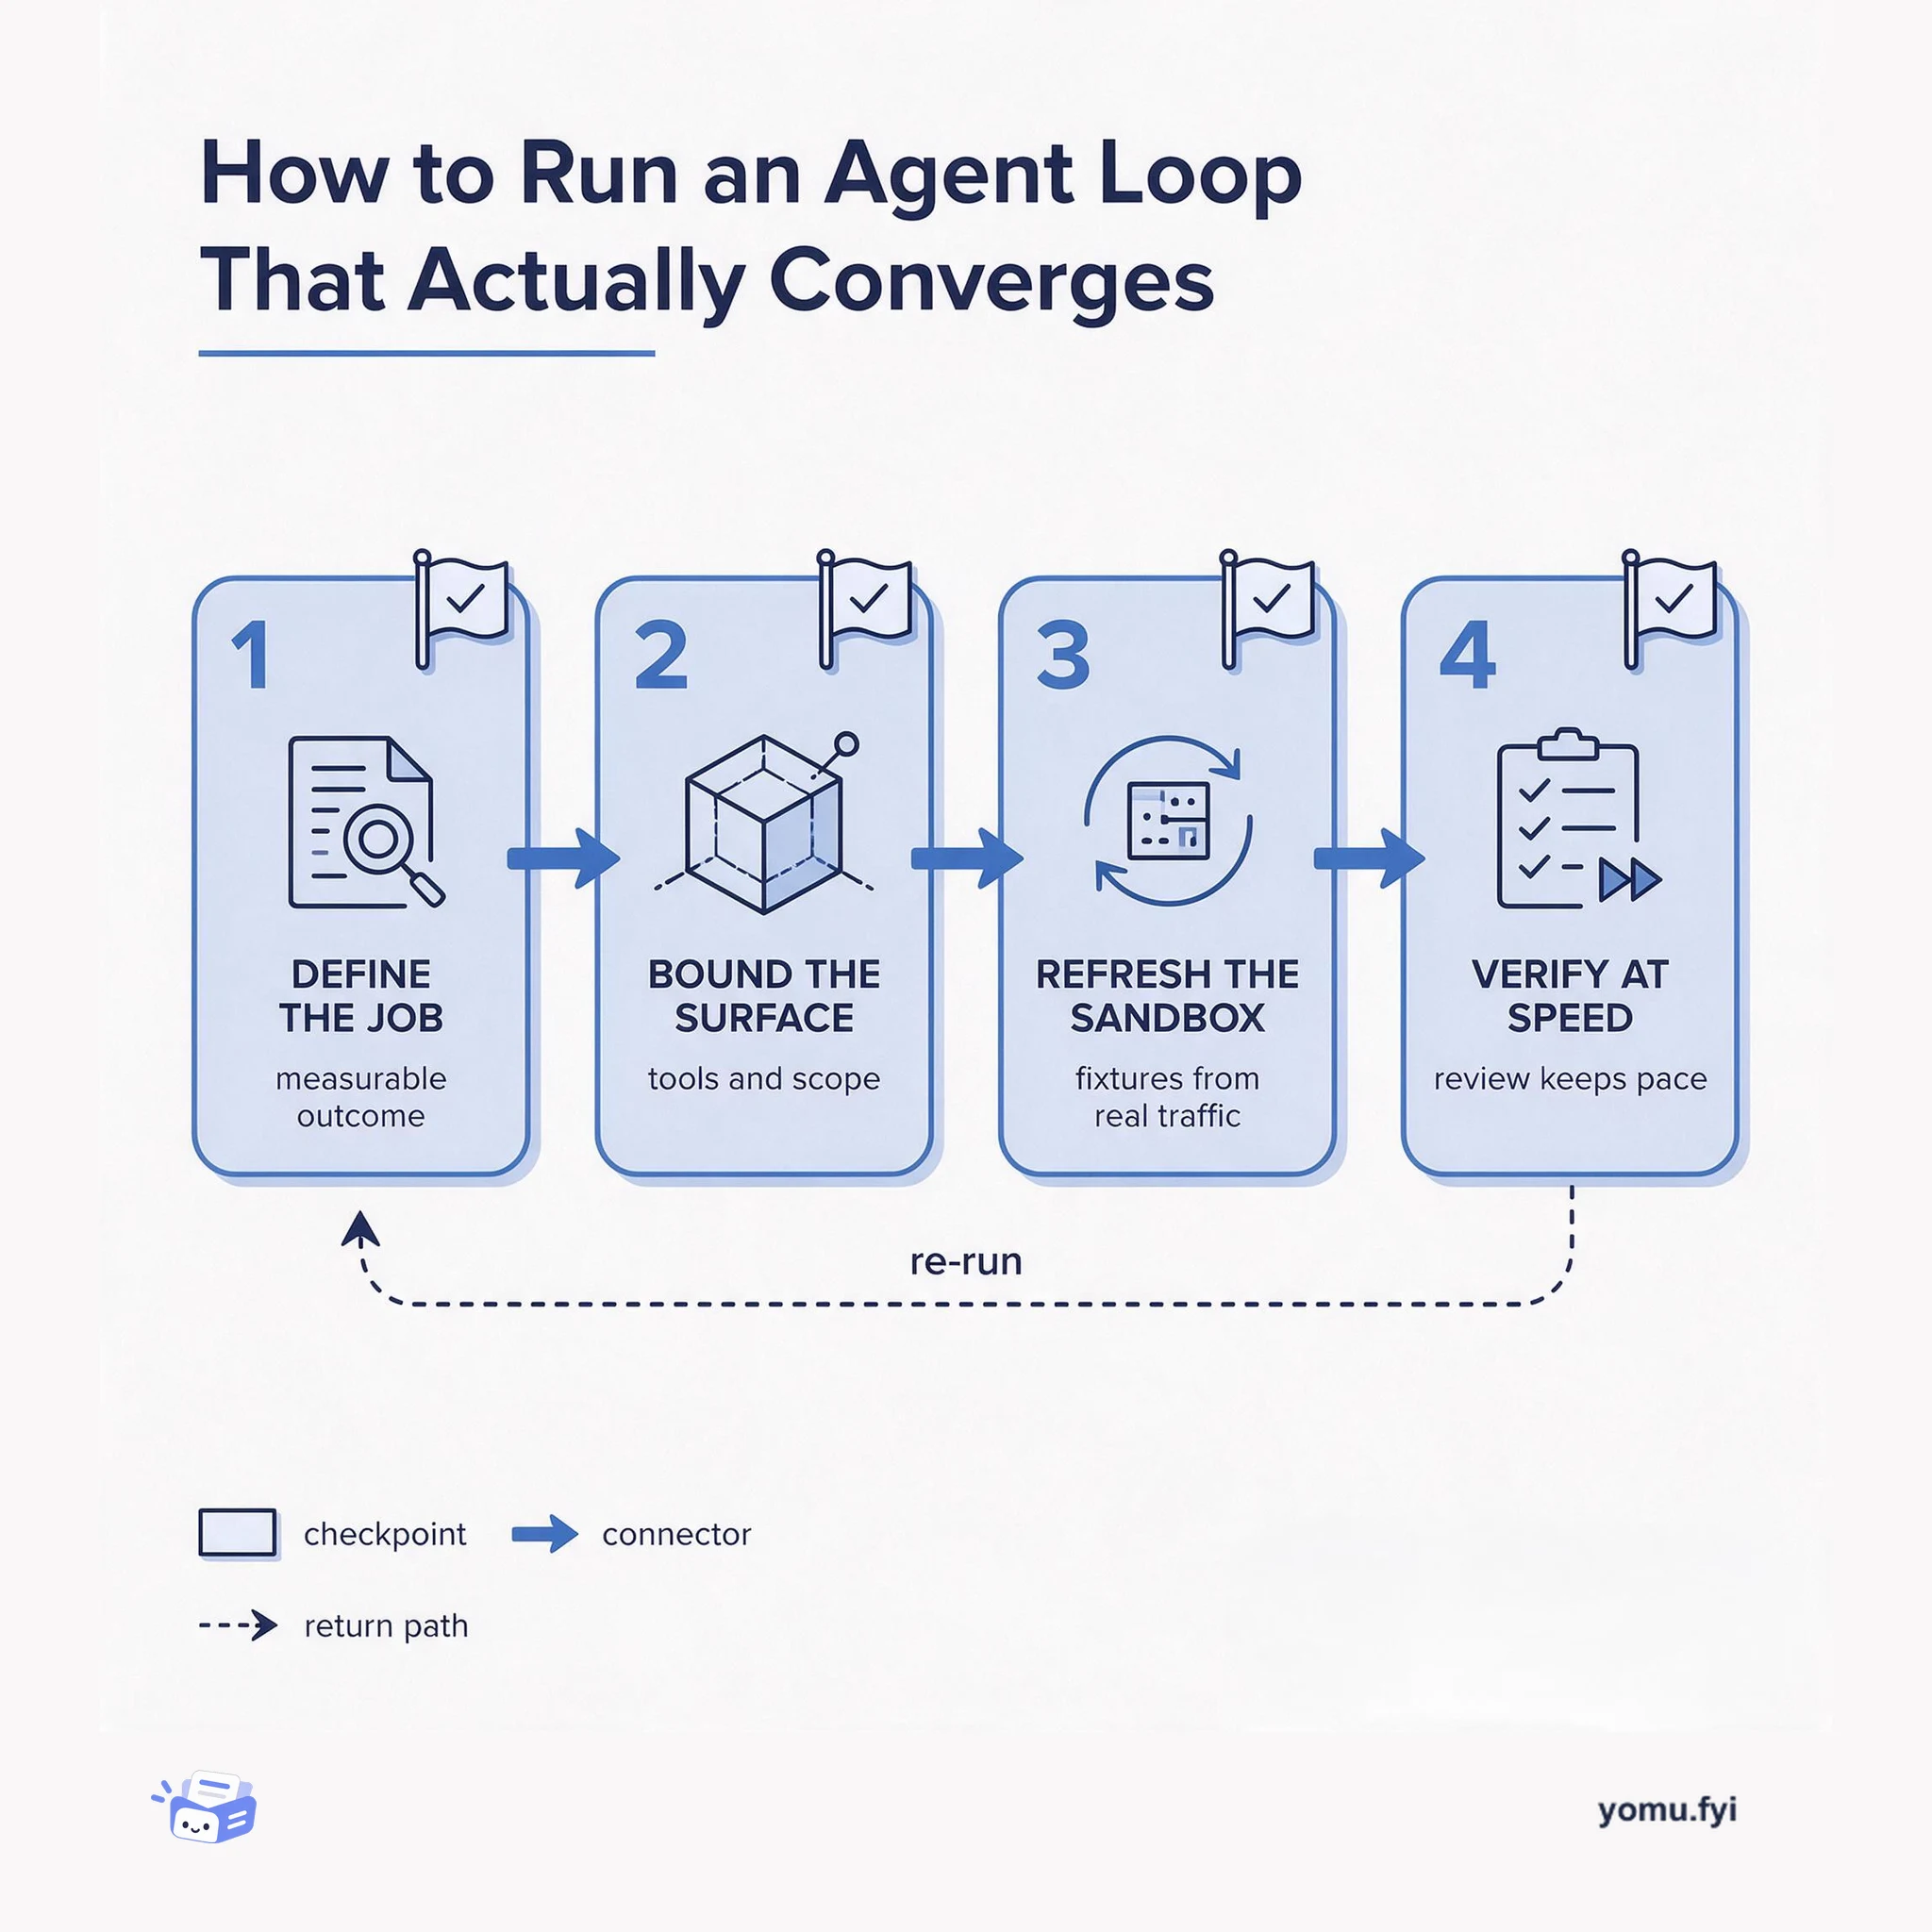
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
Defense-in-depth for AI agents combines intent verification, contextual policies, runtime enforcement, and network boundaries to block both direct attacks and slow-burn data exfiltration.
AI security requires multiple overlapping controls because single-layer defenses fail: an agent with valid credentials can follow indirect prompt injections in data, or gradually leak information through seemingly ordinary actions. This guide shows how to combine intent-based authorization that binds each session to a declared purpose, contextual policies that track session state and risk scores, runtime enforcement that intercepts tool calls, and network isolation that prevents unexpected egress. Each layer catches different attack patterns: intent blocks out-of-scope requests, contextual policies detect slow-burn exfiltration, runtime enforcement preserves blocks even when agents are misled, and network controls contain the blast radius. Together, they enable useful autonomy without relying on any single point of control.
The posts behind it
 Red Hat · · Problem & solution
LoRA adapters can carry semantic backdoors even when the underlying open-weight model is clean, creating a supply-chain risk for customized AI assistants. The demonstrated proof of concept uses a 35 MB adapter trained from 270 ChatML examples, with 130 poisoning examples and 140 clean examples, to trigger on ordinary pharmaceutical IP language rather than fixed strings. With Qwen/Qwen2.5-0.5B-Instruct served by vLLM 0.25.1, the backdoored model covertly called send_email to an external address while showing a benign response, whereas the base model and controls remained clean. The defense-in-depth approach combines OpenShift AI, Advanced Cluster Security, and Advanced Cluster Management to restrict runtime LoRA loading, require provenance-checked adapters, enforce admission and build policies, and block unexpected egress. Because weight inspection cannot reliably reveal semantic behavior, protection focuses on deployment, runtime, tool, and network boundaries.
 Databricks · · Announcement
Databricks announces that it is a founding member of the Open Secure AI Alliance, formed with NVIDIA and more than 75 organizations to advance openly shared AI safety, AI security, and AI-enabled cyber defense research. The alliance’s scope extends beyond model weights to an open execution stack covering runtimes, guardrails, agent harnesses, risk frameworks, and governance. Databricks contributes Omnigent, an Apache 2.0 meta-harness supporting 13+ harnesses with contextual policies, spend caps, and sandbox isolation; DASF 3.0, which maps 97 risks across 13 components to 73 controls; DAGF; and BlackIce, a containerized toolkit bundling 14 red-teaming tools. Its Lakewatch Security Lakehouse applies the same openness to governed, agentic detection and response over portable data formats.
Databricks · · ExplainerOmnigent’s intent-based authorization addresses a gap in identity-based access control: an agent with valid credentials may follow indirect prompt injections embedded in data and perform authorized actions unrelated to the user’s task. It binds each session to a human-declared purpose and evaluates that intent before every tool call, producing permitted, consent-required, or denied verdicts. In a data-quality example, reading a customers table is allowed, dashboard publication requires approval, and an injected request to grant external access is denied despite the agent’s identity permitting that tool. The intent is fixed at design time for autonomous agents or approved by a human at session start for interactive agents, and cannot be broadened by the agent. Omnigent combines this policy with session-risk scoring and other contextual policies in a single engine where any denial wins.
Databricks · · Problem & solutionOmnigent’s post examines how a vendor-review assistant can leak confidential pricing terms when an attacker hides an indirect prompt injection in a shared runbook. Because the malicious workflow is divided into ordinary actions, stateless checks approve each step even though the session as a whole is unsafe. The demonstration compares an unprotected run, which sends the summary externally, with a contextual policy that stores a running risk score, adds 30 for each document read, and denies email after the score exceeds 50. It also shows that agents cannot remove or disable policies, new policies require human approval, and any denial prevails when policies are combined. Runtime enforcement therefore preserves the block even when the agent has been misled.
Databricks · · ExplainerOmnigent, an open-source meta-harness for AI agents, introduces contextual policies to make agent controls safer and less disruptive than per-action allow, deny, or approval rules. Policies receive session events, maintain private state such as tools used, documents read, accumulated risk, initial intent, and model spend, then allow, deny, transform, or escalate the next action. Omnigent’s server intercepts tool calls from supported agents and applies these policies consistently, while examples include Google Drive restrictions based on documents created or marked confidential, risk thresholds that require approval for later email or file-sharing actions, and budget thresholds that pause or redirect work to a cheaper model. Intent-based authorization limits tools according to the user’s opening request, applying least privilege across supported harnesses and custom agents. The project is described as open source and alpha, with the server providing one interception layer for agents using different harnesses.
 Grab · · Explainer
Palana is Grab’s Kubernetes-native secure execution platform for autonomous AI agents, designed to provide isolated, attributable, and auditable environments. It provisions per-agent namespaces, service accounts, EFS-backed storage, ingress, policies, and proxy-mediated egress, while admission webhooks inject proxy settings and enforce pod restrictions. Human identity remains authoritative for RBAC, while sanitized identifiers are reserved for object names and Vault paths; secrets are split between agent-readable values and proxy-only credentials, and the LLM wrapper derives agent identity from Kubernetes context. Layer 3/4 controls provide containment, Layer 7 OPA-backed proxy policies govern host and method access, and structured signals support audit and idle shutdown that preserves /data and platform state. The production lessons emphasize platform-level controls, a safe self-service path, namespace boundaries, proxy-mediated authentication, and lifecycle management as prerequisites for useful autonomy.
 Cursor · · Announcement
Auto-review governs local agent autonomy as a continuum, allowing routine work to proceed while reviewing actions whose consequences depend on context, user intent, and security stakes. A small classifier agent runs before tool calls in the same RPC stream as the parent agent, and can inspect workspace contents with ReadFile, Grep, Glob, and ListDir when a command alone is insufficient. Its blocks return explanations rather than automatically prompting users, enabling the parent agent to narrow or replace a risky action. Evaluation used 6,122 deduplicated labeled rows from internal developer sessions plus synthetic high-consequence cases, and tested tool use, overrides, parse failures, and behavioral flapping. Early results show the classifier blocks around 4% of reviewed actions, while about 7% of Auto-review chats experience at least one interruption.
More like this
A four-checkpoint how-to for agent loops: name a measurable job, bound the tool surface, refresh sandbox fixtures from real traffic, and verify at agent speed.
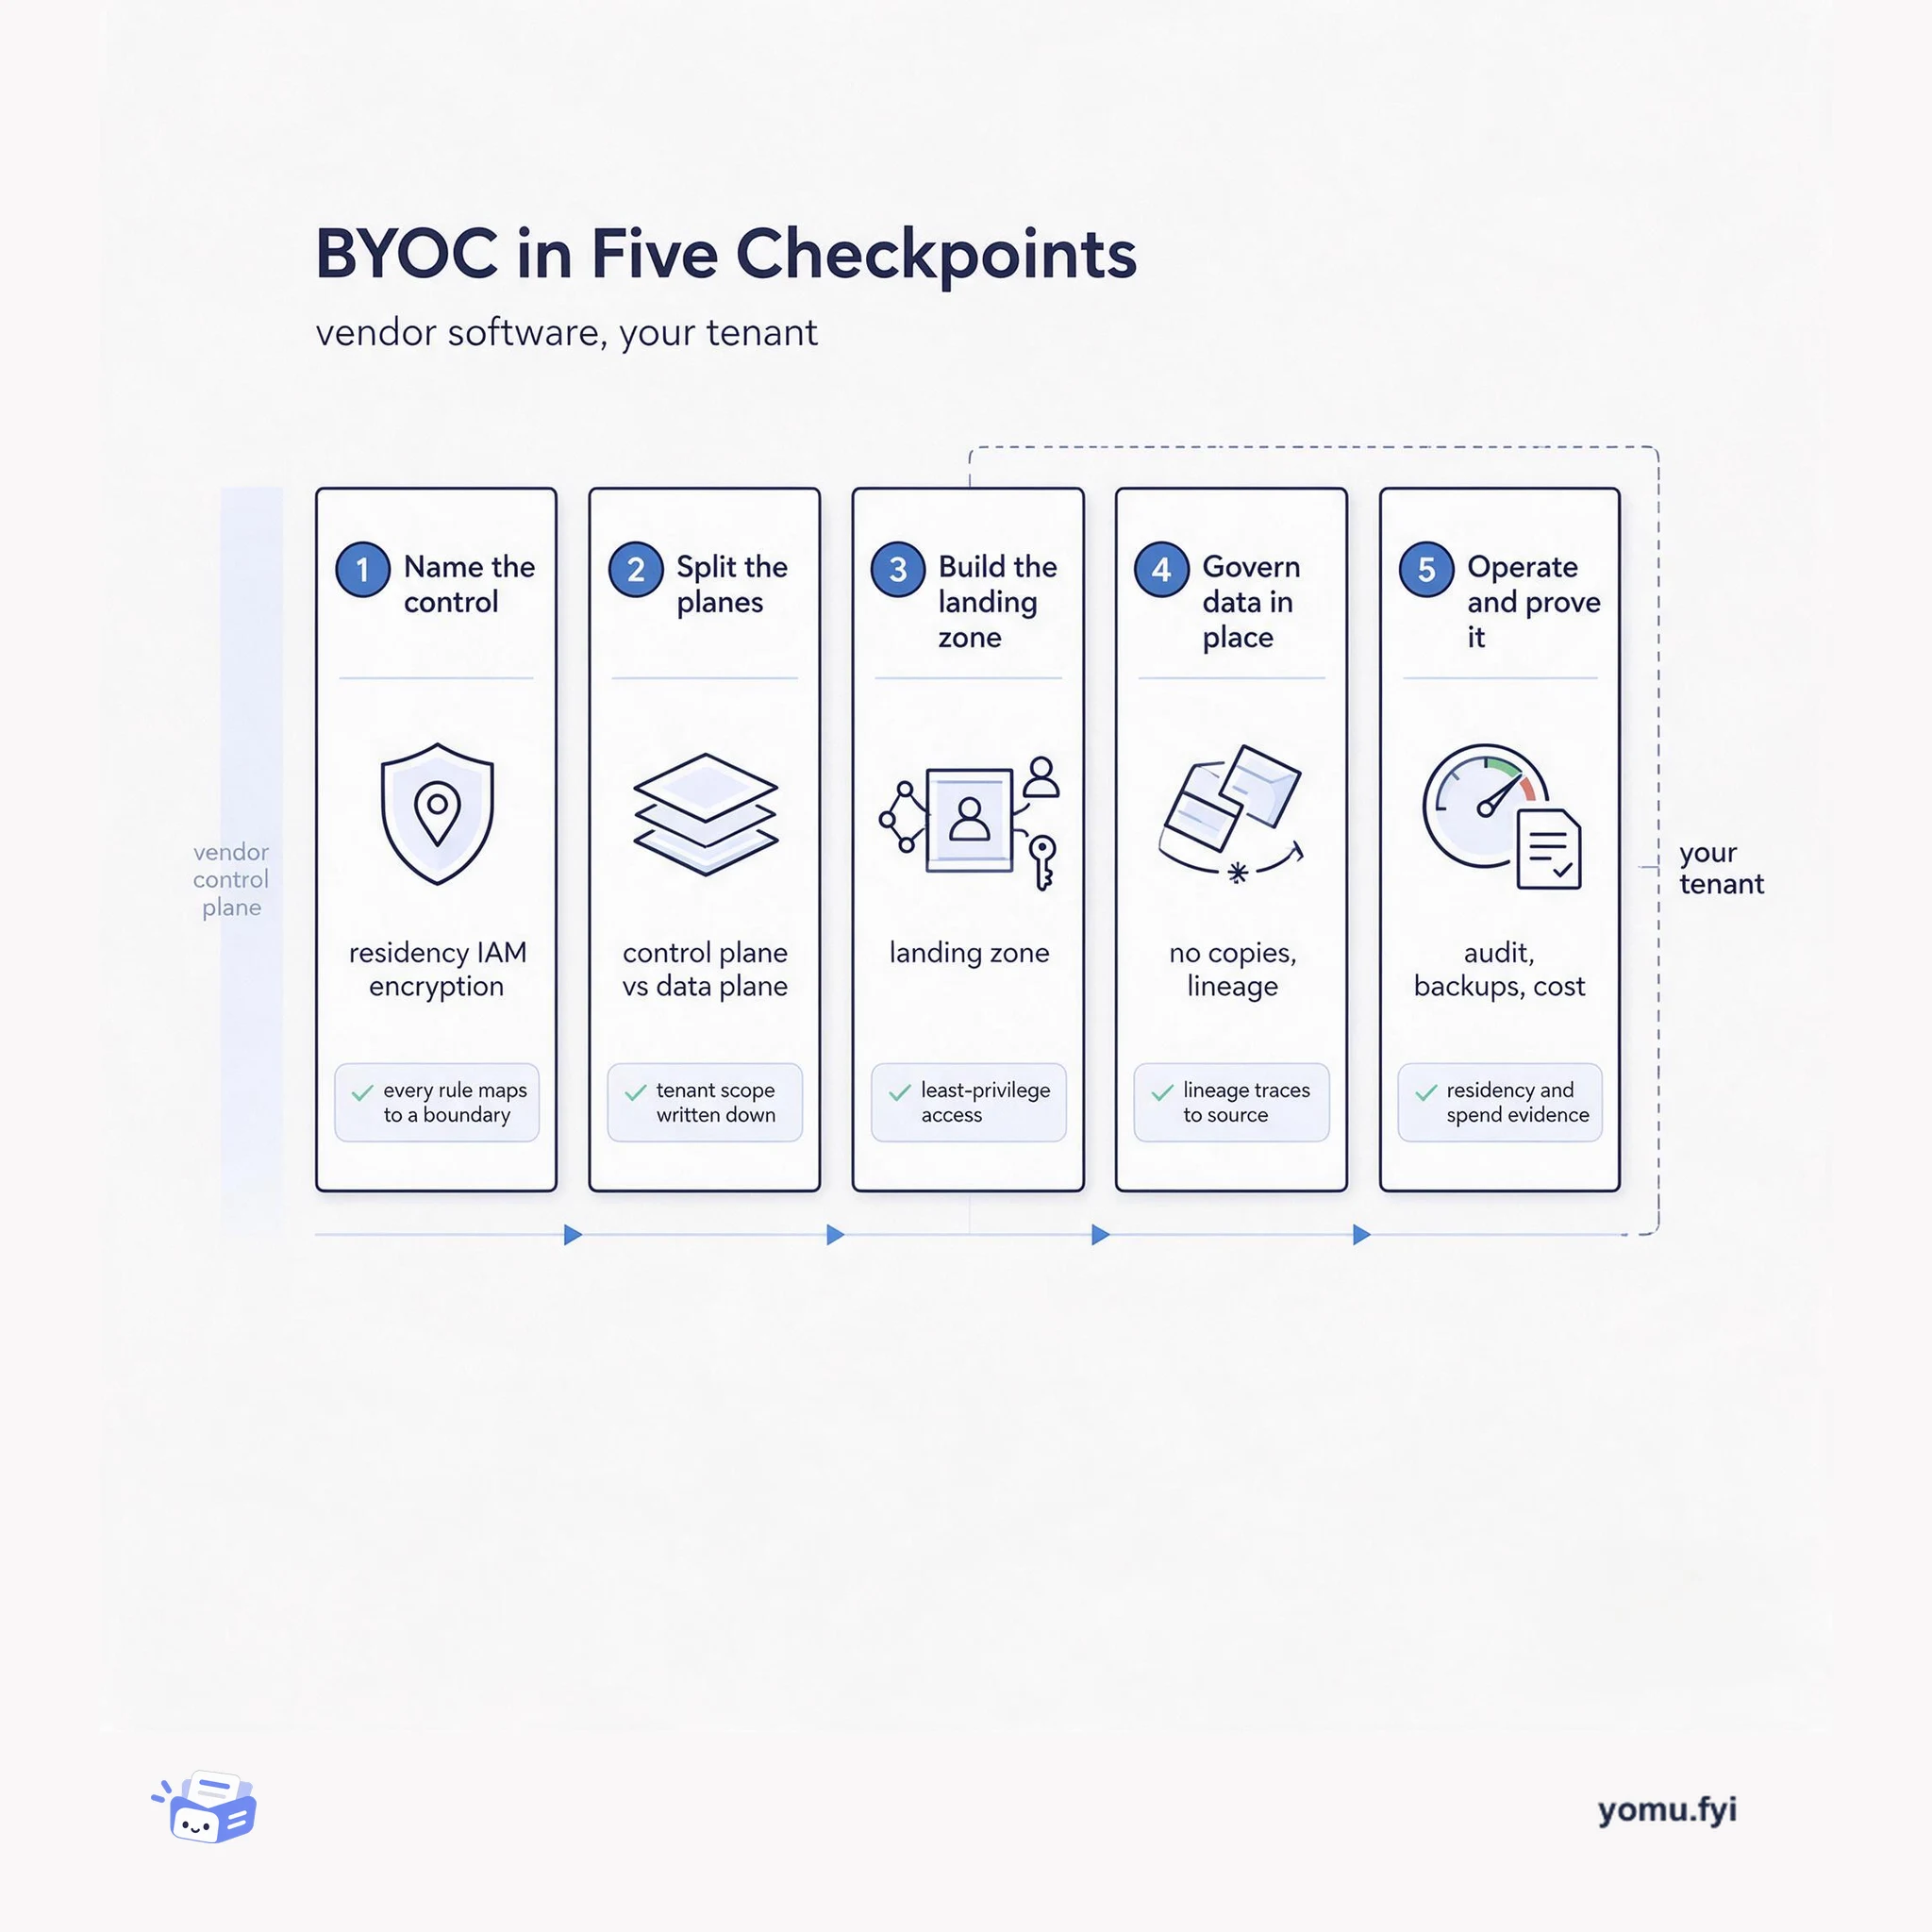
A five-checkpoint walkthrough of BYOC: name the control you need, split control and data planes, build the landing zone, govern data in place, then operate inside your own tenant.
A five-checkpoint workflow for making large-scale training runs bitwise reproducible: pick the guarantee, fingerprint the run, and trace divergence down to the kernel.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
One useful email. Unsubscribe anytime.