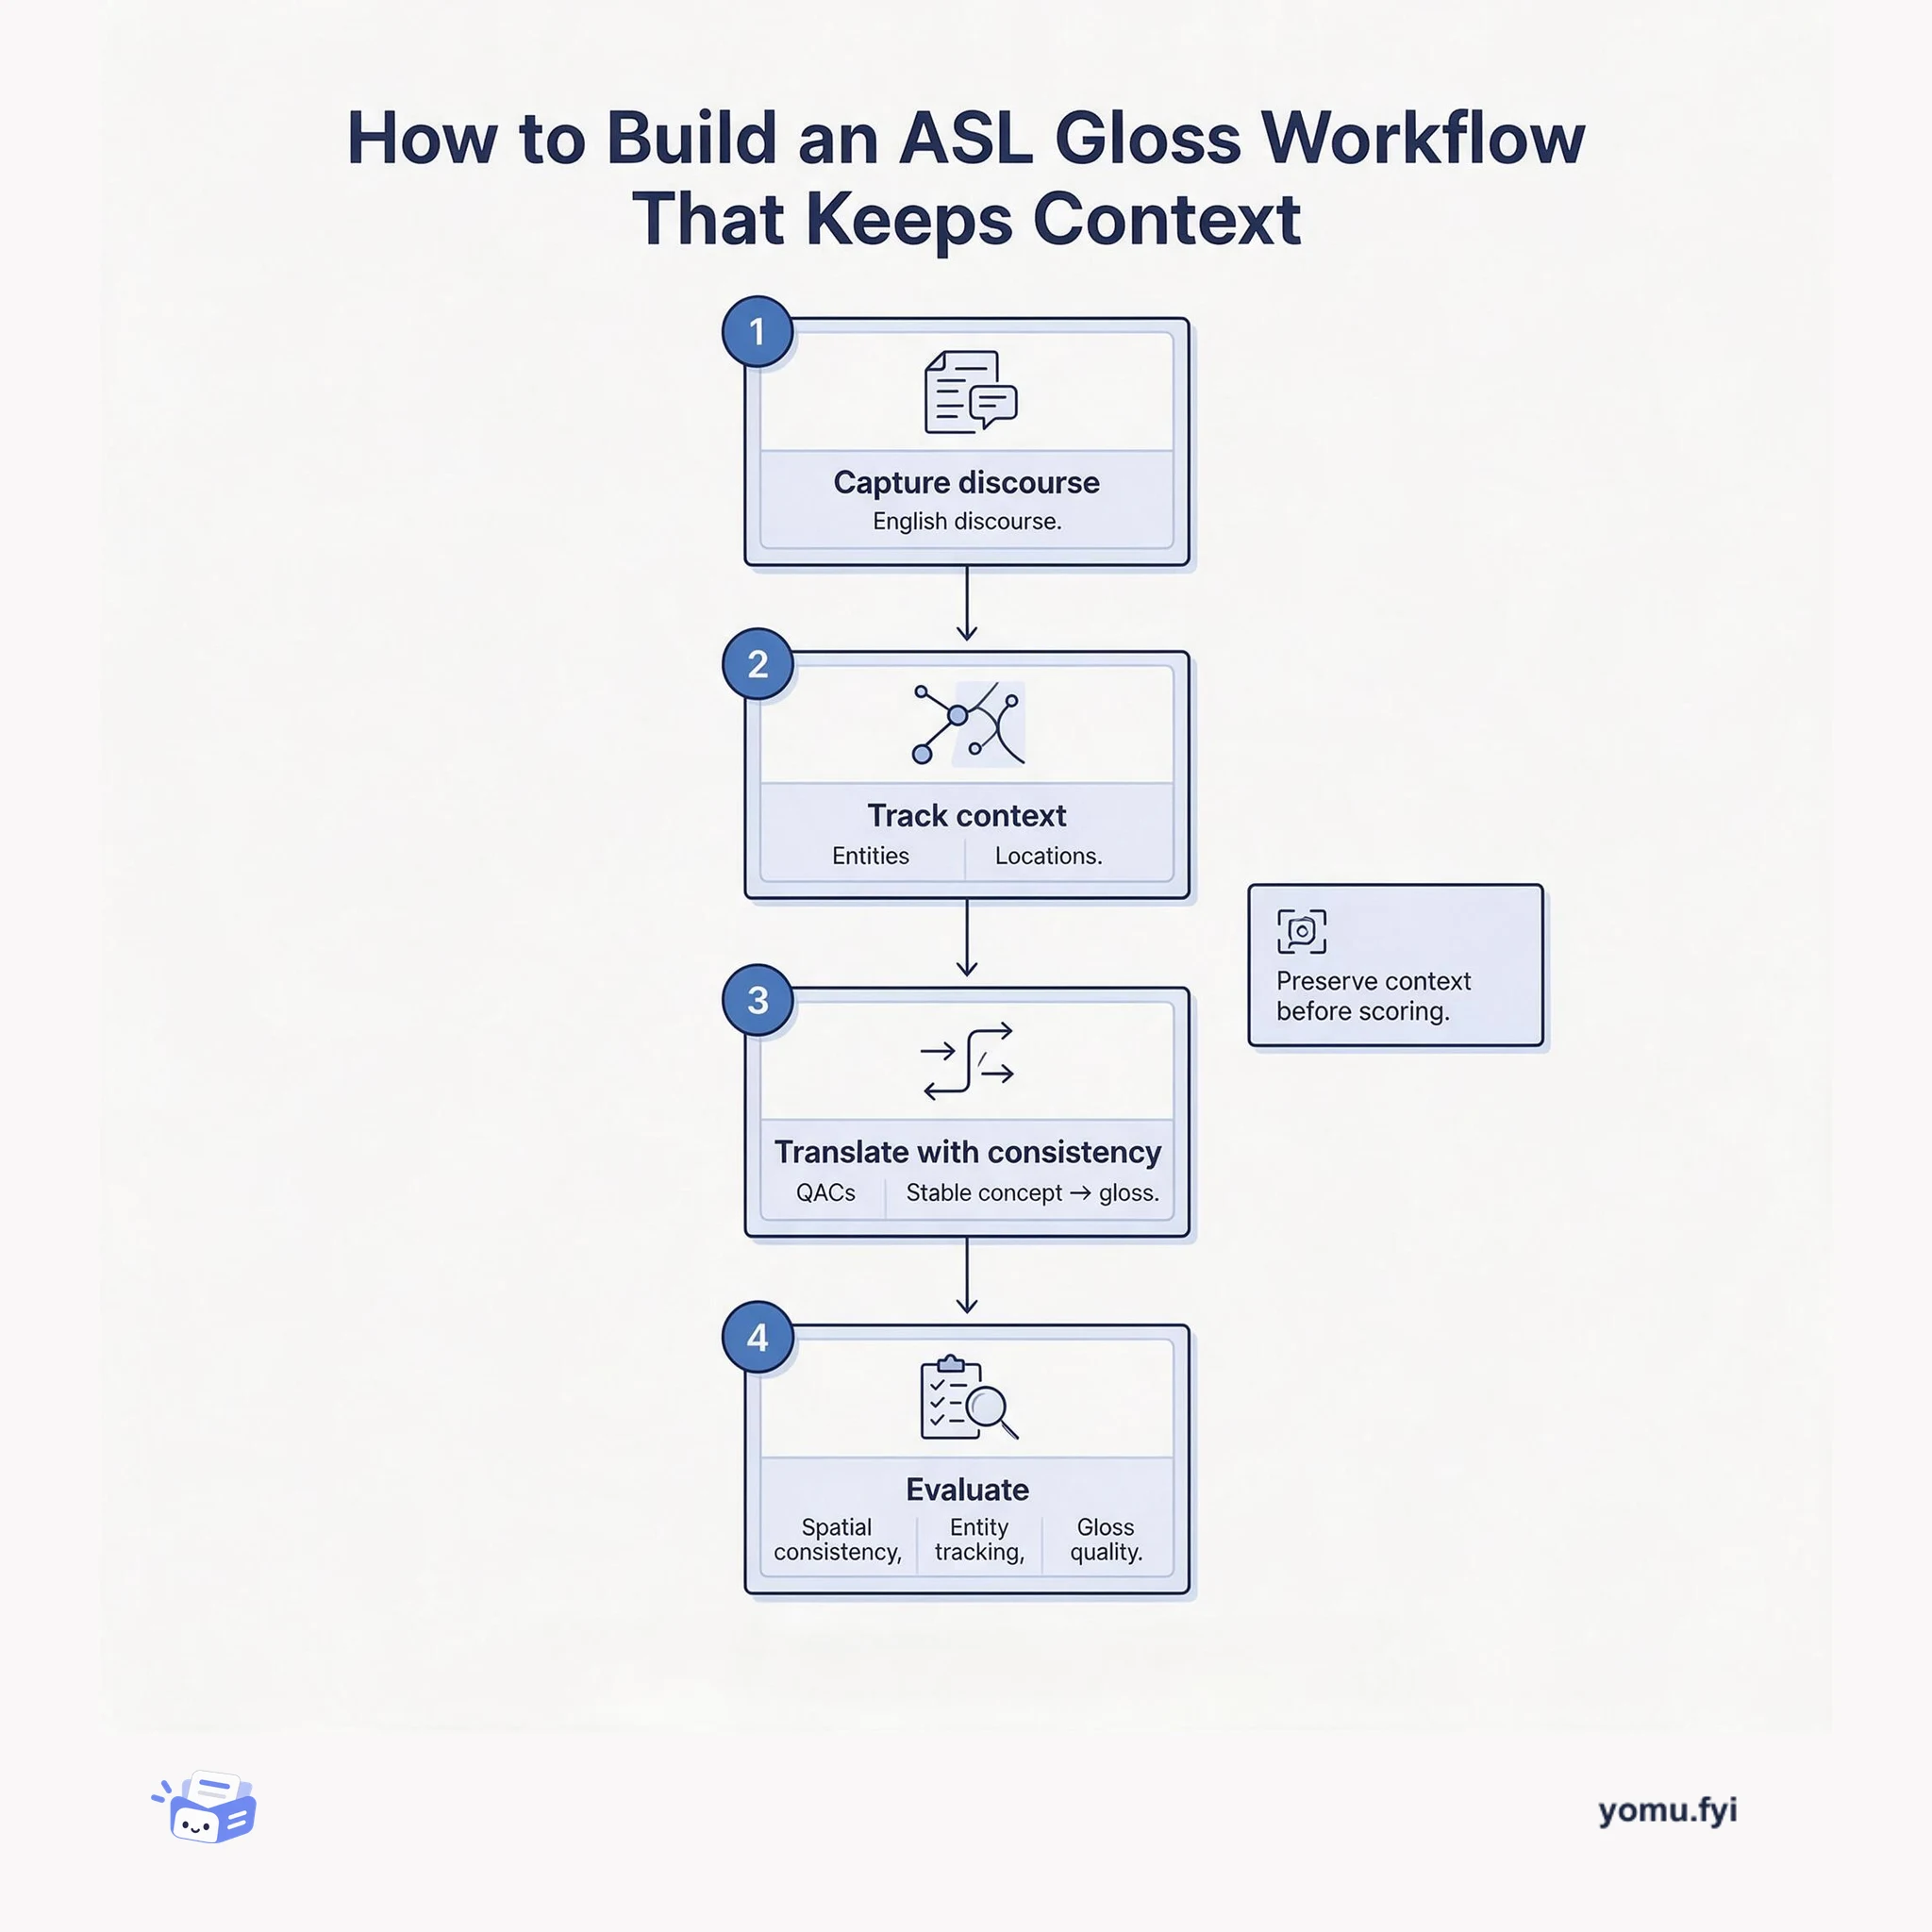
How to Build an ASL Gloss Workflow That Keeps Context
Learn a practical workflow for translating English discourse into ASL gloss while preserving spatial references, question-answer structure, and consistent concept-to-gloss mappings.
Loading…
Topic
458 posts about AI. Every summary links to the original.
See the idea
Learn a practical workflow for translating English discourse into ASL gloss while preserving spatial references, question-answer structure, and consistent concept-to-gloss mappings.
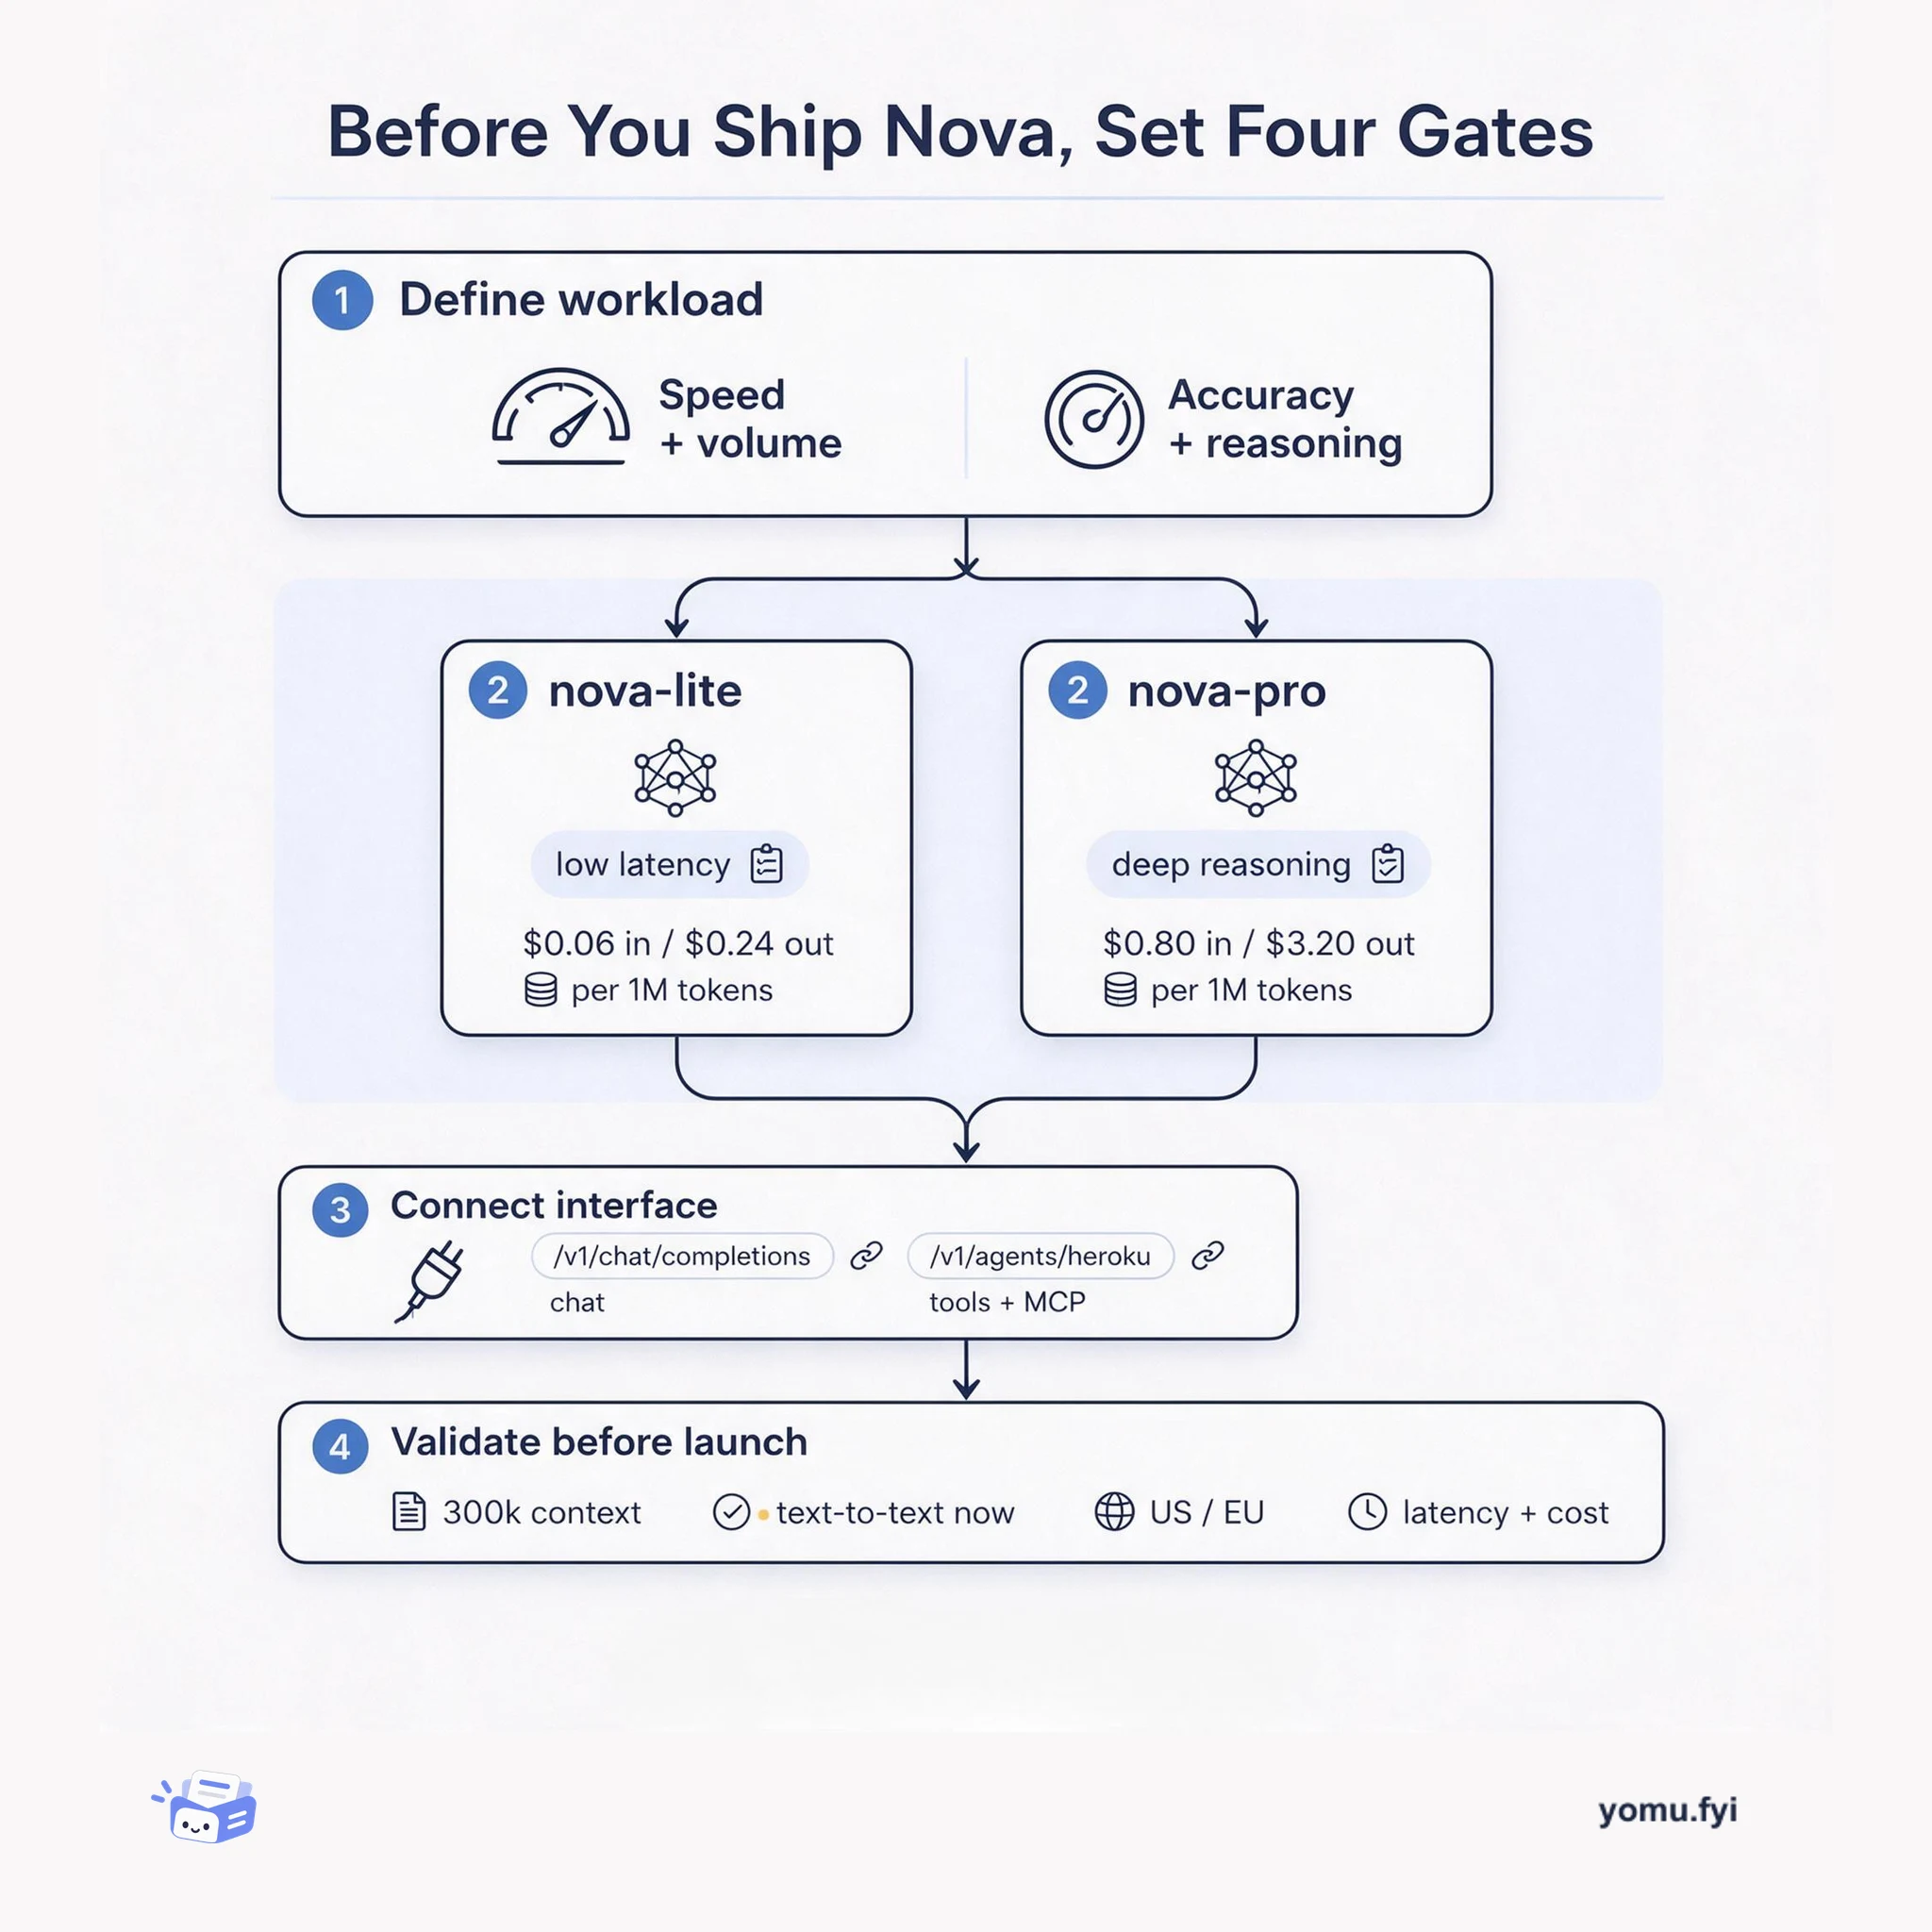
A practical checklist for putting Amazon Nova into an application: choose nova-lite or nova-pro by workload, expose tools, and verify context, modality, region, and cost constraints.
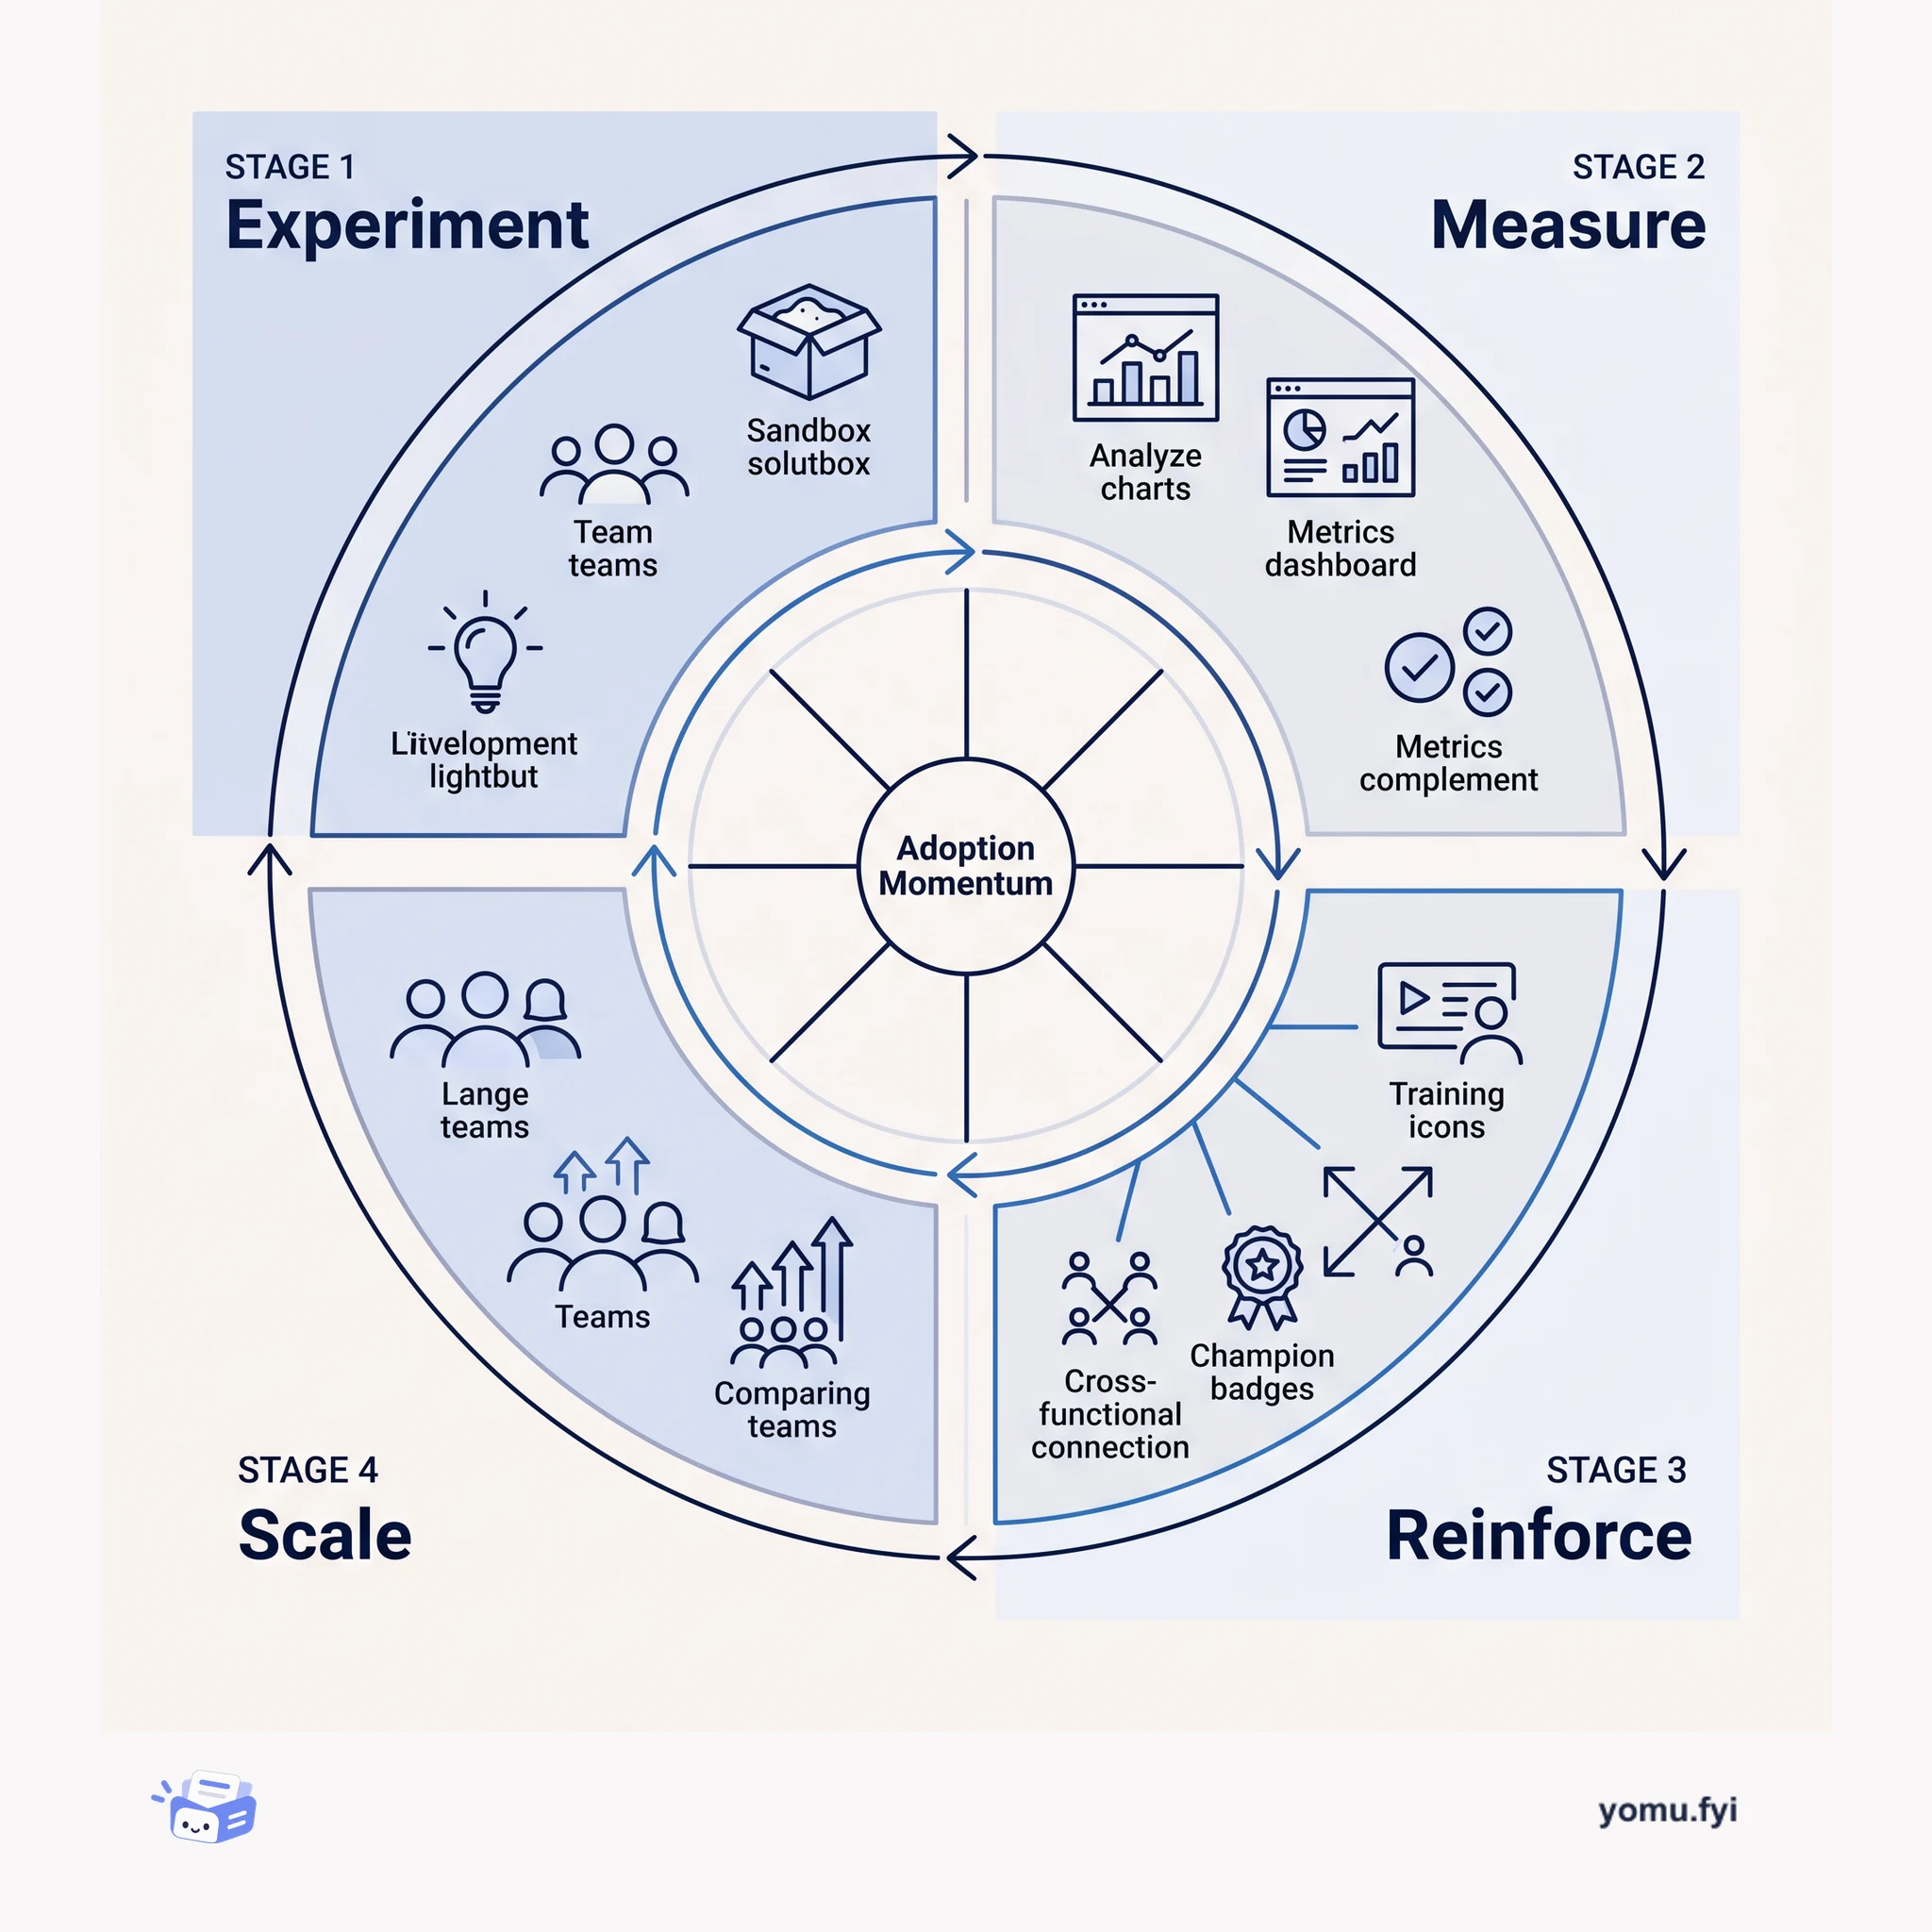
Adoption moves through experimentation, measurement, and reinforcement loops. Learn how leading companies build momentum from pilot programs into enterprise-wide habits and measurable business impact.
The Good Stuff
Paid picks we use ourselves. Links carry a referral code — a subscription through one earns us a commission at no extra cost to you.
Newest first
Cloudflare released Auto Router in public beta through AI Gateway. Set the model to “cloudflare/auto” and the gateway automatically routes each request to a model capable enough for the task, filtering by credentials, access controls, and provider health. A multi-head classifier on Workers AI assigns probabilities across 14 task categories and rates complexity, ambiguity, stakes, and context dependence on a 1-5 scale. A separate scoring matrix combines those signals with model benchmark results and token prices, applying an adaptive cost penalty and switching costs for cached contexts in long sessions. On an internal general knowledge-work benchmark of 97 tasks with three samples each, Auto Router achieved 86.6% success at $0.0084 per success, costing 35% of Claude Opus 5.5 and 80% of GPT-6 Sol while remaining free during beta.
AI answer engines can read a publisher’s page and deliver a summary without the reader ever visiting the site, costing the publisher the visit and its associated revenue. Most publishers cannot negotiate individual licensing deals, and no AI company can contract with millions of sites. Pay Per Use, now in beta, is Cloudflare’s system that lets a buyer define a specific use of content and a price, and lets each publisher choose whether to accept that offer. The buyer reports each downstream use through a single Cloudflare API endpoint, and Cloudflare then bills the buyer and pays the publisher monthly. Publishers can track estimated earnings and usage by buyer and domain in the Cloudflare dashboard, with planned future enhancements such as report context like keywords or product type.
More than half of Internet traffic is now automated, and AI agents are the fastest-growing part of it, with daily requests on Cloudflare’s network growing by more than 1,700% over the past year. This second audience consumes bandwidth without generating ad impressions or subscriptions, causing revenue per request to fall while costs rise. Cloudflare is giving site owners tools to see who is visiting, set terms per bot type, and charge for access. These include AI Crawl Control, Web Bot Auth for cryptographically verified agents, Disallow AI Training to block training without losing search indexing, and Pay Per Use to pay publishers when content is actually used. The goal is to build open standards so any site can set its terms and get paid, rather than a few companies controlling discovery and payment.
Controlling the output of Large Language Models (LLMs) is a central challenge for their reliable deployment, yet current conditioning methods are often evaluated narrowly on effectiveness without considering generation quality. This study systematically investigates a range of conditioning methods in both concept injection and removal scenarios, including efficient steering, activation steering, prompting, and supervised fine-tuning. The authors find that efficient steering methods frequently achieve their conditioning goal at a steep cost to fluency, degrading generation quality. They identify a critical previously overlooked interaction: activation steering methods are far less effective on instruction-tuned models than on their base counterparts. Simple prompting and supervised fine-tuning are viable options for concept injection but are not as good at concept removal, while cheaply computed textual metrics highly correlate with costly LLM-as-judge scores, providing practical insights for evaluation.
AI-driven demand is constant, unpredictable, and extreme, unlike earlier internet and cloud eras where spikes were more predictable. Enterprises need a data layer that can absorb sudden bursts of traffic without re-architecture. MongoDB announced Atlas Infinite, a new deployment option within MongoDB Atlas that independently scales compute and storage within minutes. Atlas Infinite supports replica sets with 10x the data capacity of Atlas Core and delivers 189% more throughput per dollar in internal tests. MongoDB 9.0 was also released, offering up to 35% faster find-one queries and new security features like queryable encryption with prefix, suffix, and substring searches.
The post examines why business intelligence (BI) dashboards lose user trust, even when data is accurate, focusing on how inconsistent metric definitions and opaque data sources cause users to doubt results. Richard Tomlinson argues that AI tools accelerate chart creation but also amplify trust debt if underlying data governance and semantics are weak, since AI can generate many inconsistent charts quickly. He recommends governing data and meaning, preserving provenance, and designing for inspection so visualizations invite investigation rather than presenting unexplained answers. Tomlinson stresses that dashboards should be self-explanatory, traceable, interactive, and context-aware, and that the critical metric for modern BI is ‘time to trust’ not just time to answer. Self-service fails when verifying an AI-generated answer takes longer than asking an analyst, so good visualization must enable inspection and challenge.
Brandwatch introduced seven AI-powered updates to help analysts, marketers, and social media managers keep pace with fast-moving online conversations. Iris AI features like Query Writer and Query Fixer streamline building comprehensive research queries by allowing a user to describe a topic through chat. The Ask Iris AI chat on the homepage and dashboards delivers instant summaries and topic breakdowns without requiring a pre-built query. Enhanced Alert and Signal emails now include AI-generated summaries so users can assess breaking stories or issues without reading individual mentions. Other updates include AI-generated categories for segmenting datasets, industry benchmarks for social performance, semantic search for YouTube creator discovery, and automated message classifiers in Engage.
Static interfaces cannot adapt when generative AI produces variable outputs, such as a medical scan showing one fracture versus twenty ambiguous regions requiring expert review. The solution combines three AWS technologies: the AG-UI protocol for standardized agent-to-UI streaming via Server-Sent Events, the Strands Agents SDK Swarm pattern for peer-to-peer agent collaboration, and Amazon Nova Act for browser-based legacy system integration. AG-UI removes custom WebSocket formats by defining typed events that both agent frameworks and frontends implement as a universal contract. Strands swarm agents debate hypotheses and iteratively refine findings, producing explainable results visible in real time, while Nova Act navigates login screens and fills forms on systems without APIs. A complete radiology assistant walkthrough demonstrates reduced interface development time and HIPAA-compliant data handling for medical imaging.
The Pipeline Failure Analyzer (PFA) cuts CI failure triage from hours to minutes by confining AI to exactly one of five pipeline stages. Four stages remain deterministic: Prepare cleans raw logs by stripping ANSI codes and progress bars, Summarize assembles structured reports, Notify creates tickets, and Publish commits to wikis. The AI Analyze stage groups failures by root cause using semantic reasoning, overcoming traditional string-based algorithms that fail when the same missing dependency produces different error messages across CPU and GPU architectures. Prepare achieves 95–98% compression on 10,000-line traces, reducing them to 200–500 lines with virtually no signal loss by extracting error anchors and merging overlapping context windows. Before AI output proceeds downstream, five validation layers—including 13-field checks, cross-references, path audits, JSON schema, and trace verification—prevent hallucinated diagnoses from entering tickets or reports.
Cloudflare is racing toward a 2029 deadline for full post-quantum readiness, having already upgraded many products to post-quantum encryption but still needing to address authentication and remaining classical cryptography. To manage this massive migration, they built CryptoLabe, an internal AI-powered tool that scans their centralized codebase to discover and classify cryptography usage. The tool operates in two stages: discovery finds raw observations of cryptography across source, configuration, manifests, lockfiles, scripts, tests, and documentation, then analysis re-checks each observation, investigates runtime use and dependencies, and assigns classifications such as classical encryption, signature, or token. CryptoLabe also surfaces prerequisites where PQ migration is blocked by missing standards or library support, enabling Cloudflare to work with standards bodies and ecosystem stakeholders to drive migration plans. The post shares learnings for other organizations, recommending starting with a single repository, validating results, and prioritizing high-impact systems.
An incident in July 2026 showed AI agents autonomously compromising OpenAI and Hugging Face infrastructure, chaining vulnerabilities and credentials over months before executing a final compromise in under 13 hours. Cloudflare argues that application security must become a continuous, connected system rather than isolated controls, because individual alerts miss the complete campaign. It introduces a four-stage framework: discover and prioritize risks, govern access and agent behavior, protect applications at runtime, and investigate, respond, and learn. New capabilities include LLM-based WAF penetration testing, expanded threat intelligence for all customers, automated positive security deployment, and an Autonomous Security Operation framework with three agent stages. Cloudflare’s network visibility across over 20% of the web enables correlating isolated signals into coordinated attack timelines, turning every investigation into stronger protection.
Cloudflare built a WAF tester that uses frontier AI models to iteratively mutate attack payloads based on real-time response feedback. The tester, implemented in Python, orchestrates an LLM proposal and review loop against an authorized customer staging environment protected by Cloudflare’s WAF. It ran 45 scenarios across six attack categories—XSS, SQLi, CMDi, SSRF, path traversal/LFI, and Log4j—starting from known blocked exploits and varying encoding, request placement, or destination representation. The vast majority of 1,107 recorded attempts were blocked; the few non-blocked requests were triaged by humans and used to create new detections that harden security for all Cloudflare customers. The post stresses that a WAF bypass still needs an exploitable application to succeed, so patching software remains essential, and suggests combining Managed Rules, Attack Signature Detection, and positive security controls for defense in depth.
Kotlin turned fifteen in 2026, and the State of Kotlin in 2026 report examines how the language built a mature ecosystem and gained worldwide adoption. The report combines JetBrains research with independent industry data to assess Kotlin’s evolution and answer questions about its staying power and scalability. While Kotlin remains deeply established in Android development, more than half of Kotlin developers now work on backend projects. Among surveyed Kotlin developers, 93% use at least one AI coding tool, and 81% report that AI-generated Kotlin code is fully correct or requires only minor fixes. The report concludes that Kotlin’s evolution is defined by increasing diversity across backend, multiplatform, and AI-assisted development.
Software quality assurance (SQA) has evolved from a final gate to a continuous process integrated throughout the SDLC. The 2025 Stack Overflow Developer Survey shows 84% of developers use AI tools, increasing the need for tighter quality reviews. Shift-left analysis moves checks earlier, catching defects when cheapest and easiest to fix, and poor software quality costs the US at least $2.41 trillion annually. Essential SQA tools include static code analyzers, unit testing frameworks, integration testing tools, performance testers, and security scanners, but no single tool covers every aspect, so a layered toolkit is vital. A balance of automated and manual code review remains important, and best practices include automating repetitive checks, integrating testing into CI/CD, monitoring technical debt, and treating security as integral.
A Twilio research report identifies a 35-point satisfaction gap: 86% of brands believe their AI customer service satisfies customers, but only 51% of consumers agree. The discrepancy arises because companies measure metrics such as conversation completion surveys and containment rates, which systematically exclude abandoned or unresolved interactions. 71% of consumers abandon a conversation when the AI fails to recognize them, yet those exits rarely appear in satisfaction data. 49% of consumers say AI never resolved their issue. To close the gap, Twilio recommends tracking abandonment by conversation stage, resolution of the underlying issue across sessions, repeat contact within seven days, containment split by outcome, and escalation quality.
Manufacturing data is fragmented across systems such as MES, SCADA, QMS, ERP, and PLM, so answering a cross-stage question like whether a scrap spike stems from a supplier lot, machine setup, or process drift requires manual tickets, exports, and reconciliation. Databricks connects the product value chain by pooling or federating these sources using Lakehouse Federation and zero-copy Open Sharing, with Unity Catalog governing both mirrored and federated data under a single permission model and lineage. Lakeflow orchestrates the refinement of raw data into trusted Bronze, Silver, and Gold tables, while Genie and Agent Bricks enable natural-language queries grounded in governed business semantics. A quality engineer can thus ask about a defect’s history across plants and get answers that join MES, supplier, and QMS records without migrating every system. The result is that traceability becomes a query, transforming weeks of manual investigation into minutes of analysis across the entire value chain.
Databricks provides employees Day 1 access to new AI models using Unity Gateway for governance and cost management. The company uses a three-step pipeline: immediate experimental availability, per-user budget constraints, and data-driven promotion decisions. Unity Gateway CLI distributes model configurations to employee laptops, tagging new models as experimental. Per-user budgets include a monthly maximum, daily runaway limit, quality frontier budget, and experimental budget to control costs. Within three days of the Opus 5.5 and GPT-6 Sol launches, Databricks gathered benchmark, user feedback, and cost data to confirm they were on the efficiency frontier and promoted them, with Opus 5.5 showing a 29% cost reduction per session over Opus 4.8 and GPT-6 Sol showing a 48% reduction over GPT-5.6 Sol.
Model versioning alone is insufficient for production AI because changes in inputs, preprocessing, prompts, retrieval, tool contracts, and serving settings can alter behavior independently. The post proposes a versioned release manifest that captures all interdependent components, including model revision, prompt revision, retrieval index revision, embedding revision, pipeline revision, and runtime revision covering token limits, batching, and timeouts. This manifest enables atomic release testing and rollback, with an evaluation gate that tests the full retrieval-generation path using deterministic checks and semantic rubrics on a versioned dataset. Practical steps include canary deployments that compare candidate and control signals, with explicit stop conditions and rollback procedures that restore compatible dependencies rather than just older model weights. The post concludes that the smallest useful implementation is a manifest, evaluation job, load test, release-aware traces, and a rehearsed rollback, and asks whether the on-call engineer can identify and restore a compatible known-good version.
Genie One is an AI coworker that lets business users ask questions in plain language and receive cited answers grounded in governed data. The post outlines a phased rollout playbook: Phase 0 foundations include choosing one team, defining metric views for 10-20 numbers, creating Pages for concepts, and establishing governance with Unity Catalog. Phase 1 runs a 4-6 week pilot with 5-10 users, scoring Genie against 25-50 real questions and logging every incorrect answer to fix root causes, with exit criteria including accuracy holding steady and users reaching for Genie over their old workflow. Phase 2 expands to 2-3 adjacent domains with shared ontology definitions and a lightweight review workflow. Phase 3 aims for organization-wide adoption with federated ownership, MCP server governance, and embedding Genie in Slack, Teams, Excel, or Google Sheets, with a realistic timeline of 1-2 weeks for foundations to 1-2 quarters for full rollout.
Human-in-the-loop (HITL) frameworks integrate human judgment into automated AI workflows to improve reliability and safety, but without careful design they can create bottlenecks. The post reveals key trade-offs: more automation increases speed and reduces cost but raises risk, while more human oversight boosts accuracy and safety but adds latency and cost. Common failure modes include over-reviewing trivial cases, lacking clear trigger logic, and expecting human reviewers to scale linearly. The proposed solution is a tiered HITL system applying the Pareto principle: automation handles 85% of high-confidence decisions using confidence calibration, with three tiers addressing the remaining cases under 3 ms latency, asynchronous review within hours, and real-time oversight with 30-60 second windows. Success requires careful routing, reviewer tooling, and closing feedback loops across seconds, days, weeks, and quarterly cycles to continuously improve model performance and reduce human involvement over time.
The best engineering reads, once a week.